
AI may be software, but the infrastructure behind it is increasingly specialised hardware.
Every large language model, inference platform and enterprise AI workload ultimately depends on physical compute: GPUs, high-performance networks, storage and the engineers who make those systems work together reliably.
That has created one of the fastest-developing disciplines in infrastructure recruitment: the GPU cluster engineer.
In the UK, GPU and HPC engineers can now command some of the highest salaries in hands-on infrastructure engineering, particularly where candidates have experience operating large NVIDIA estates, high-performance networking or production AI clusters.
At TTC Group, we recruit GPU cluster, HPC, networking and AI infrastructure engineers for compute providers, data centre operators, integrators and enterprise infrastructure teams across the UK and Europe.
This guide explains what GPU engineers earn in 2026, what contractors can charge, which skills command the highest salaries and what employers are currently looking for.
How Much Does a GPU Engineer Earn in the UK in 2026?
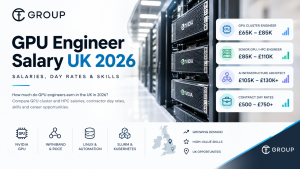
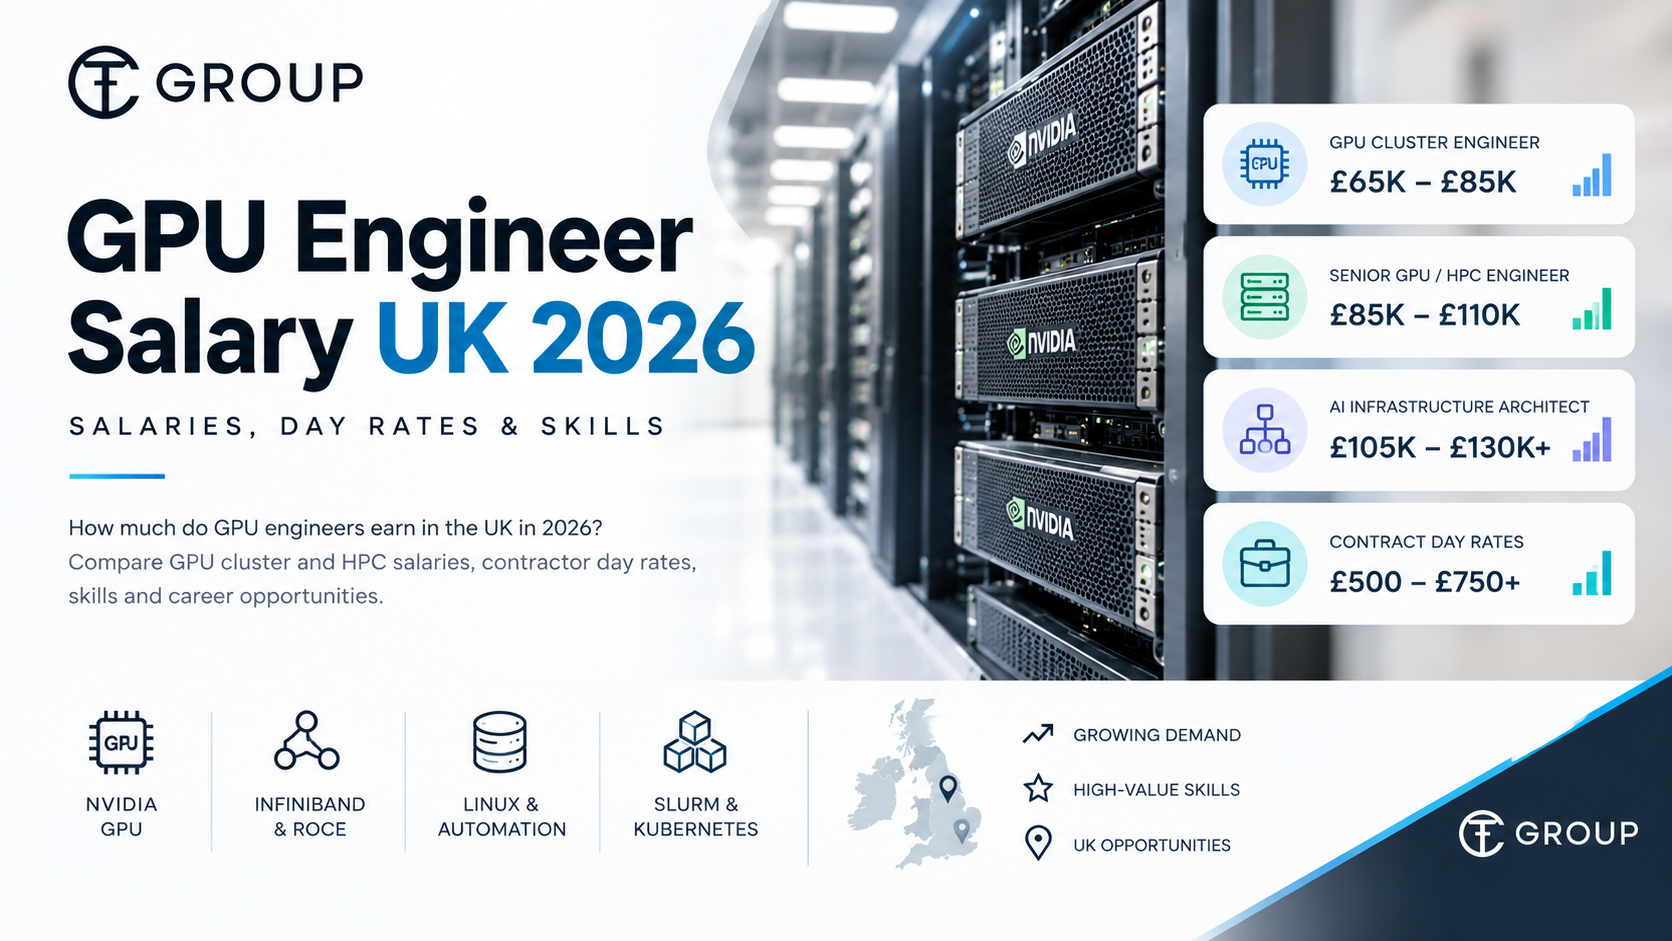
GPU cluster and HPC engineers in the UK typically earn between £60,000 and £110,000+ in 2026, with senior specialists in large AI compute, hyperscaler and neocloud environments potentially earning £120,000 or more.
Typical salary ranges are:
| Experience | Indicative UK Salary |
|---|---|
| Junior / Developing GPU Infrastructure Engineer | £55,000–£70,000 |
| GPU Cluster Engineer | £65,000–£85,000 |
| Senior GPU / HPC Engineer | £85,000–£110,000 |
| Lead GPU / HPC Engineer | £100,000–£120,000+ |
| AI Infrastructure Architect | £105,000–£130,000+ |
These figures should be treated as market guidance rather than fixed salary bands.
Compensation varies considerably depending on the size of the GPU estate, the networking environment, location, employer type and whether the engineer is supporting research, enterprise infrastructure or commercial AI compute.
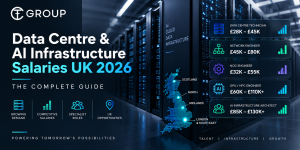
For a wider comparison across infrastructure disciplines, see our UK Data Centre & AI Infrastructure Salary Guide 2026</ a>.
Why Are GPU Engineer Salaries So High?
GPU infrastructure sits at the intersection of several technical disciplines.
A traditional systems engineer may specialise mainly in servers and operating systems. A network engineer may focus on switching, routing and connectivity.
A GPU cluster engineer often needs to understand both — plus orchestration, accelerators, storage and workload performance.
The scarcity becomes clearer when you look at how rapidly AI infrastructure is expanding.
CBRE reported that AI-focused colocation capacity signings across Europe reached 420MW during the first half of 2026, compared with just 89MW during the same period in 2025.
In the UK, hyperscalers and neocloud operators are increasingly acquiring capacity capable of supporting AI workloads, while London data centre take-up is expected to remain at historically strong levels.
The hardware can be purchased.
Finding engineers who know how to operate it at scale is harder.
What Does a GPU Cluster Engineer Actually Do?
A GPU cluster engineer designs, deploys, operates and optimises computing environments built around GPUs.
Their responsibility is not simply installing graphics cards into servers.
At scale, GPU infrastructure behaves more like a distributed supercomputer.
Typical responsibilities include:
- Deploying GPU nodes and compute clusters
- Managing Linux environments
- Configuring high-performance networking
- Supporting NVIDIA GPU platforms
- Managing Slurm or Kubernetes
- Monitoring cluster utilisation
- Troubleshooting compute and networking bottlenecks
- Maintaining drivers, firmware and software stacks
- Supporting distributed storage
- Diagnosing failed nodes and hardware
- Automating infrastructure deployment
- Improving GPU utilisation and workload performance
A GPU cluster worth millions of pounds creates very little value when the accelerators are idle.
This is why cluster utilisation, resilience and troubleshooting experience can be extremely valuable to employers.
TTC recruits these specialists through our AI Infrastructure & Data Centre Recruitment practice.
GPU Engineer vs HPC Engineer: What’s the Difference?
There is significant overlap between GPU engineers and HPC engineers.
HPC — high-performance computing — predates the current AI boom.
HPC engineers traditionally worked with compute clusters used for scientific research, modelling, engineering, pharmaceuticals, weather forecasting and academic research.
AI infrastructure has borrowed heavily from the HPC world.
The difference is often the workload.
An HPC engineer may support:
- CPU and GPU compute clusters
- Scientific workloads
- Research computing
- Parallel processing
- Slurm environments
- MPI workloads
- High-performance storage
A GPU infrastructure engineer is more likely to focus on:
- NVIDIA GPU estates
- AI model training
- Inference infrastructure
- Machine-learning workloads
- GPU cloud platforms
- AI compute-as-a-service
- Large-scale accelerator clusters
In reality, many of the most valuable engineers in today’s market have experience in both HPC and AI infrastructure.
That is also why employers frequently struggle when searching by job title alone.
TTC’s approach is to source these professionals by technical capability and project experience rather than relying solely on titles.
How Much Do GPU Engineers Earn as Contractors?
Experienced GPU and HPC contractors can command strong day rates, particularly where projects require proven large-scale production experience.
| Contractor Level | Indicative Day Rate |
|---|---|
| Infrastructure / Linux Engineer | £350–£500/day |
| GPU Cluster Engineer | £500–£650/day |
| Senior GPU / HPC Engineer | £600–£750/day |
| Specialist Architect / Consultant | £700–£900+/day |
Highly specialised projects can exceed these ranges.
The highest rates are typically associated with engineers who can demonstrate experience delivering or troubleshooting large production clusters rather than simply having theoretical knowledge of the technologies involved.
Contract demand is particularly common during:
- New GPU cluster deployments
- Data centre fit-outs
- Infrastructure migrations
- Capacity expansions
- Commissioning
- Hardware refreshes
- Emergency troubleshooting
- Performance optimisation
TTC supports both permanent hiring and contract technology recruitment across AI infrastructure and data centre environments.
Which GPU Infrastructure Skills Pay the Most?
Not all GPU engineers command the same salary.
The strongest compensation tends to follow skill combinations that are difficult to find together.
1. NVIDIA GPU Infrastructure
Experience operating NVIDIA GPU environments remains highly valuable.
Relevant knowledge can include:
- NVIDIA GPU architecture
- CUDA
- NVIDIA drivers
- NVIDIA Fabric Manager
- NVIDIA GPUDirect
- DGX platforms
- NVLink
- NCCL
- GPU monitoring and telemetry
Experience with large production estates matters more than simply knowing the product names.
2. InfiniBand
InfiniBand is one of the most important technologies within large-scale AI and HPC clusters.</ p>
It provides very high-bandwidth, low-latency communication between compute nodes.
Engineers with practical experience configuring and troubleshooting InfiniBand fabrics can therefore command a significant premium.
TTC’s AI Infrastructure practice specifically recruits network engineers with expertise in InfiniBand, RoCE and high-performance Ethernet.
3. RoCE
RoCE — RDMA over Converged Ethernet — allows remote direct memory access across Ethernet networks.
It is increasingly important in AI infrastructure because GPU clusters need extremely high-throughput east-west connectivity.
Strong RoCE engineers understand areas such as:
- Congestion management
- PFC
- ECN
- Lossless Ethernet
- RDMA
- Latency
- Fabric design
Engineers who understand both conventional data centre networking and AI fabrics are particularly valuable.
4. Slurm
Slurm remains one of the most widely used workload schedulers in HPC environments.
Engineers who understand Slurm can manage:
- Compute allocation
- Workload scheduling
- Resource queues
- Job prioritisation
- Cluster utilisation
As organisations transition traditional HPC environments towards GPU-heavy AI workloads, Slurm knowledge is increasingly transferable.
5. Kubernetes
Not every AI infrastructure environment uses Slurm.
Many organisations increasingly use Kubernetes to orchestrate GPU workloads, particularly where AI infrastructure sits closer to cloud-native application environments.
Engineers who understand both Kubernetes and physical GPU infrastructure can bridge two traditionally separate teams.
This also creates crossover with TTC’s Cloud & Platform Engineering Recruitment practice.
6. Linux
Linux may be the least glamorous item on the list, but it remains one of the most important.</ p>
Large GPU environments depend heavily on Linux.
Strong candidates usually have deep experience with:
- System administration
- Kernel troubleshooting
- Networking
- Automation
- Drivers
- Performance analysis
- Scripting
- Operating-system debugging
A GPU engineer who cannot troubleshoot Linux at depth will quickly hit limitations in a production cluster.
7. Automation
Infrastructure operating at scale cannot be managed manually.
Experience with technologies such as:
- Ansible
- Terraform
- Python
- Bash
- Infrastructure as code
- Automated provisioning
can materially improve a candidate’s value.
Automation becomes particularly important as GPU estates grow from dozens of accelerators to hundreds or thousands.
What Qualifications Help GPU Engineers Earn More?
There is no single qualification required to become a GPU engineer.
Employers generally place more weight on production experience than certifications.
However, relevant qualifications can help demonstrate technical capability.
These may include:
- NVIDIA certifications
- Linux certifications
- Cisco CCNP or equivalent networking certifications
- Kubernetes certifications such as CKA
- Cloud certifications from AWS, Azure or Google Cloud
- HPC-specific training
- Networking qualifications
For experienced candidates, evidence of successfully deploying and operating large compute environments generally carries more weight than certification alone.
Do GPU Engineers Need to Know Networking?
Yes — increasingly so.
One of the biggest differences between conventional server infrastructure and large AI clusters is the importance of east-west network traffic.
AI training workloads require GPUs across multiple machines to communicate extremely quickly.
Network performance can therefore directly affect GPU utilisation.
If a cluster contains expensive accelerators but the network becomes the bottleneck, a substantial amount of compute capacity can be wasted.
This is why organisations are increasingly looking for people with combined expertise across:</ p>
GPU + Linux + networking + orchestration.
Those profiles are difficult to find — and therefore expensive.
Does Location Affect GPU Engineer Salaries?
Yes, although specialist AI infrastructure roles are somewhat less geographically uniform than traditional IT positions.
London and the South East remain major centres for UK data centre and infrastructure activity.
At the same time, new infrastructure investment is broadening into regions such as Oxfordshire, the North East, Wales and other areas where power and development capacity are available.
For the most specialist GPU engineering positions, technical experience can have a larger influence on salary than postcode alone.
Are GPU Engineers in Demand in the UK?
Yes.
The growth of AI infrastructure is creating demand from several different types of organisation.
TTC recruits GPU and HPC professionals for:
- GPU cloud providers
- Neocloud platforms
- AI compute providers
- Data centre operators
- HPC integrators
- Technology OEMs
- Hyperscalers
- AI companies and model developers
- Universities and research institutions
- Enterprise HPC teams
These organisations do not all hire the same type of engineer.
A research institution may prioritise Slurm and scientific computing.
A neocloud may prioritise GPU utilisation, cluster automation and NVIDIA infrastructure.
A hyperscaler may need engineers operating much larger estates.
That is why candidates should avoid thinking of GPU engineer as one standardised job description.
What Are the Most Valuable GPU Engineer Skill Combinations?
GPU + InfiniBand
Ideal for large-scale AI and HPC clusters.
GPU + RoCE
Increasingly valuable where organisations run AI workloads over high-performance Ethernet.</ p>
GPU + Slurm
Strong combination for HPC, research and large training environments.
GPU + Kubernetes
Useful for AI cloud platforms and production machine-learning infrastructure.
GPU + Linux + Automation
A powerful foundation for virtually any cluster environment.
GPU + Storage
Large-scale AI workloads require enormous data throughput, making storage performance increasingly important.
GPU + Data Centre Operations
Particularly valuable for organisations building and operating their own physical compute infrastructure.
How Can a Systems Engineer Move Into GPU Infrastructure?
Engineers do not necessarily need to begin their careers as GPU specialists.
Many move into the discipline from adjacent infrastructure roles.
A common progression might look like:
Linux / Systems Engineer → Infrastructure Engineer → HPC / Cluster Engineer → GPU Infrastructure Engineer → Senior GPU Engineer / Architect
Network engineers can make a similar transition:
Network Engineer → Data Centre Network Engineer → High-Performance Network Engineer → AI Fabric / GPU Network Specialist
The important step is gaining exposure to live compute environments.
Candidates who can demonstrate that they have deployed, operated or troubleshot real clusters are substantially more attractive than those whose experience is purely academic.
GPU Engineer Salary vs Other Infrastructure Roles
GPU engineering currently sits towards the upper end of the infrastructure salary market.
| Role | Typical UK 2026 Salary |
|---|---|
| Data Centre Technician | £28,000–£45,000+ |
| NOC Engineer | £32,000–£55,000+ |
| Data Centre Network Engineer | £45,000–£80,000+ |
| GPU / HPC Engineer | £60,000–£110,000+ |
| AI Infrastructure Architect | £85,000–£130,000+ |
For the complete comparison, see TTC’s Data Centre & AI Infrastructure Salaries UK 2026 guide.
Hiring GPU Cluster or HPC Engineers?
Finding GPU engineers is difficult because the best candidate may not actually have GPU Engineer written anywhere on their CV.
They may describe themselves as:
- HPC Engineer
- Linux Cluster Engineer
- Research Computing Engineer
- Infrastructure Engineer
- Platform Engineer
- Systems Engineer
- HPC Systems Administrator
- AI Infrastructure Engineer
- Network Engineer
That is why TTC maps the market around capability rather than job titles.</ p>
Our AI Infrastructure & Data Centre Recruitment team recruits across:
- GPU cluster engineering
- HPC
- InfiniBand
- RoCE
- High-performance networking
- NOC operations
- Data centre engineering
- Commissioning
- Rack & stack
- Smart hands
TTC provides candidate profiles within 24 hours of a requirement and fills most infrastructure roles within 48–72 hours.
Building a GPU cluster or struggling to find specialist infrastructure talent? Talk to TTC Group.
Frequently Asked Questions
1. How much does a GPU engineer earn in the UK?
2. How much does a GPU engineer earn per day?
3. What does a GPU cluster engineer do?
4. Is GPU engineering the same as HPC?
5. Are GPU engineers in demand?
6. Do GPU engineers need a degree?
7. Which GPU infrastructure skills pay the most?
8. What is the difference between a GPU engineer and an AI engineer?
Methodology
Salary and day-rate ranges in this guide are indicative TTC Group market benchmarks for 2026 and are intended to provide general market guidance rather than guaranteed compensation figures.</ p>
Ranges reflect TTC’s recruitment experience across AI infrastructure and data centre roles, alongside advertised vacancies and wider infrastructure market data.
Market demand context has been cross-checked against 2026 UK and European data centre research showing continued expansion of AI-oriented infrastructure capacity and increasing demand from hyperscalers and neocloud providers.